
Cooma TokenFactory
Inside the token factory.
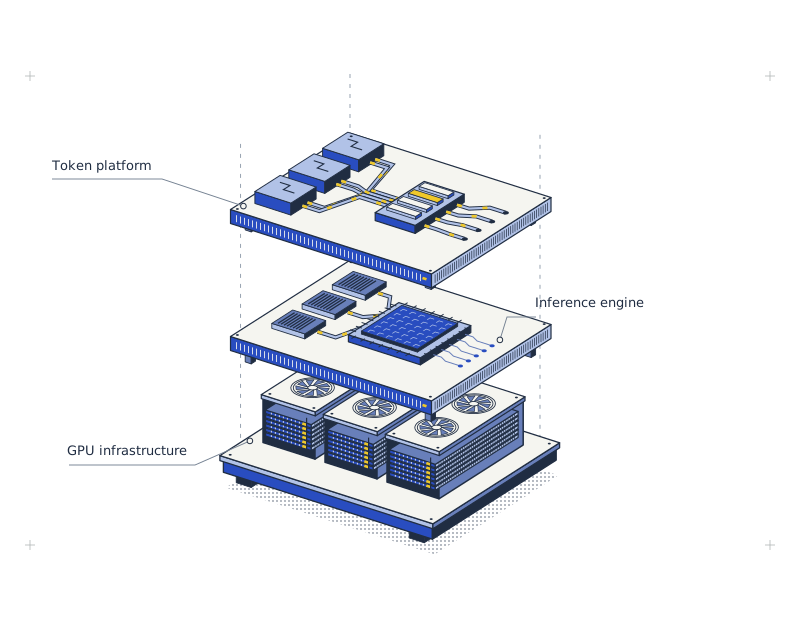
Follow a request through the software Cooma operates. See how a GPU cluster serves your model and how its output reaches your application.
The technology
How a GPU hour becomes tokens.
-
GPU infrastructure
Cooma brings rented bare metal into service, connects storage and networking, and monitors the cluster that runs your model.
-
Inference engine
The engine loads the model, processes prompts and generates tokens. Batching requests and reusing shared prompt computation can increase useful output per GPU hour. The right settings depend on your model, response time and quality requirements.
-
Token platform
Your application receives output through the API. Project keys control access, limits govern consumption, and usage records show which project used the tokens.
Bulk offtake
Your models. A dedicated cluster.
Contract for the entire output of a cluster running your models for an agreed term. We size the deployment around model version, expected traffic, location and service levels.
For wholesale platforms and aggregators, we can supply tokens from spare capacity where the contract permits. The dedicated buyer’s service takes priority.
Discuss token supplyInfrastructure
GPU and system platforms
We confirm the configuration, quantity and location with our infrastructure partners for each deployment.
| Platform | Cooma availability |
|---|---|
| NVIDIA H100 | By arrangement |
| NVIDIA H200 | By arrangement |
| NVIDIA B300 | By arrangement |
| NVIDIA GB300 | Coming soon |
| NVIDIA Vera Rubin | Coming soon |
Supplier regions
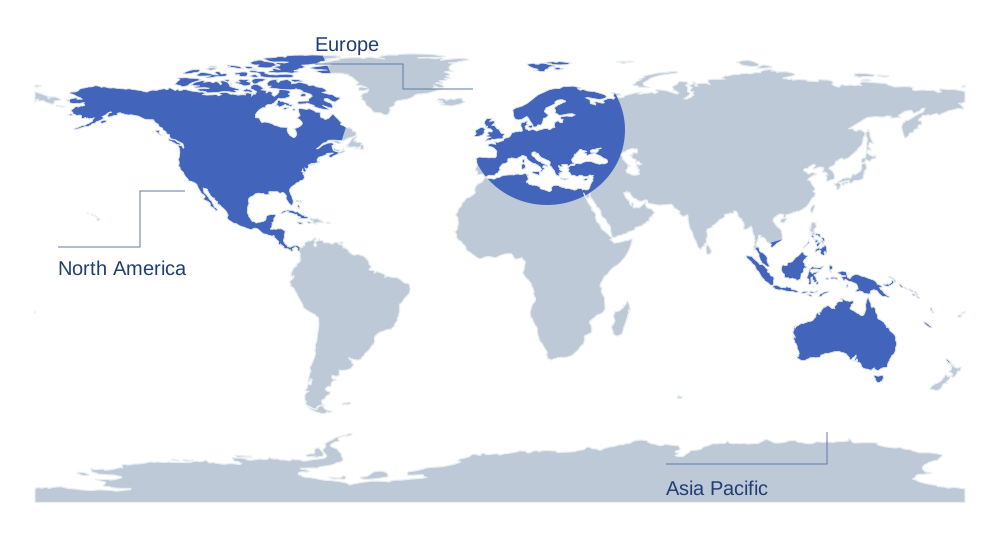
Where we source capacity.
We work with infrastructure suppliers across North America, Europe and Asia Pacific. For each engagement, Cooma confirms the facility, available hardware and where the workload will run.
Model as a Service
Need an API key?
Access selected models through Cooma’s portal. For provider-hosted models, the provider runs inference and Cooma manages access and usage.
Explore Model API