
Cooma TokenFactory
Token supply
for AI platforms.
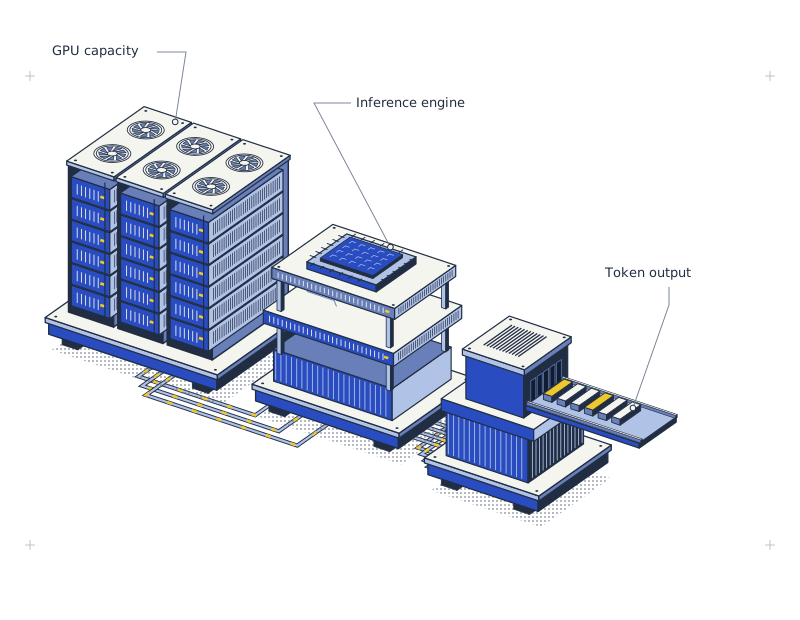
We run your models on dedicated GPU capacity sourced from infrastructure partners. You buy the token output your platform needs.
Dedicated production
One cluster for your models.
For model companies and platforms with sustained demand, Cooma sources a cluster, loads your models and operates inference for an agreed term. A bulk offtake agreement gives you the cluster’s entire token output.
How dedicated supply worksModel as a Service
Build with the Model API.
For teams and individual developers who need access to selected models. Use a project key, set limits, and track token usage through the Cooma portal.
Explore Model API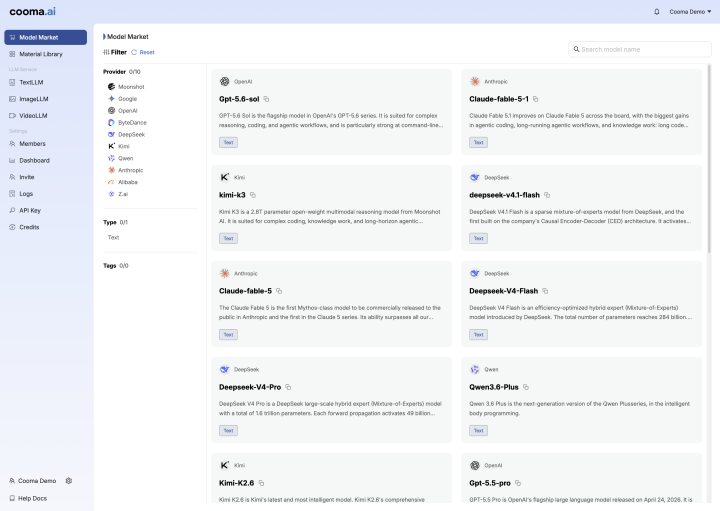
Insights